TASMAYU
SWAIN

Undergraduate AI researcher · deep nets, llms & representation alignment
swaintasmayu [at] gmail [dot] com

// about

Tasmayu Swain

I am Tasmayu Swain, a B.Tech CSE student at MAIT (2024–2028) based in New Delhi. I work on understanding and extending the fundamental properties of Large Language Models — loss landscapes, parameter symmetries, and representation alignment.

Most of my time goes into empirical research: reproducing research papers, then pushing them until they break. My current thread is generalized linear mode connectivity — how far parameter symmetry alignment actually reaches for transformers once you move out of distribution, change depth, regularize weight matching, or pick adversarial endpoints.

Beyond that I like model scalability, Deep RL , Diffusion Language Models, architecture reimplementation from scratch (MoE routing, latent attention) , scientific ML.

> stack

PythonPyTorchTensorFlowHugging FaceLangChainRAGLLM Fine-tuningDeep LearningNLPDocker

// research papers

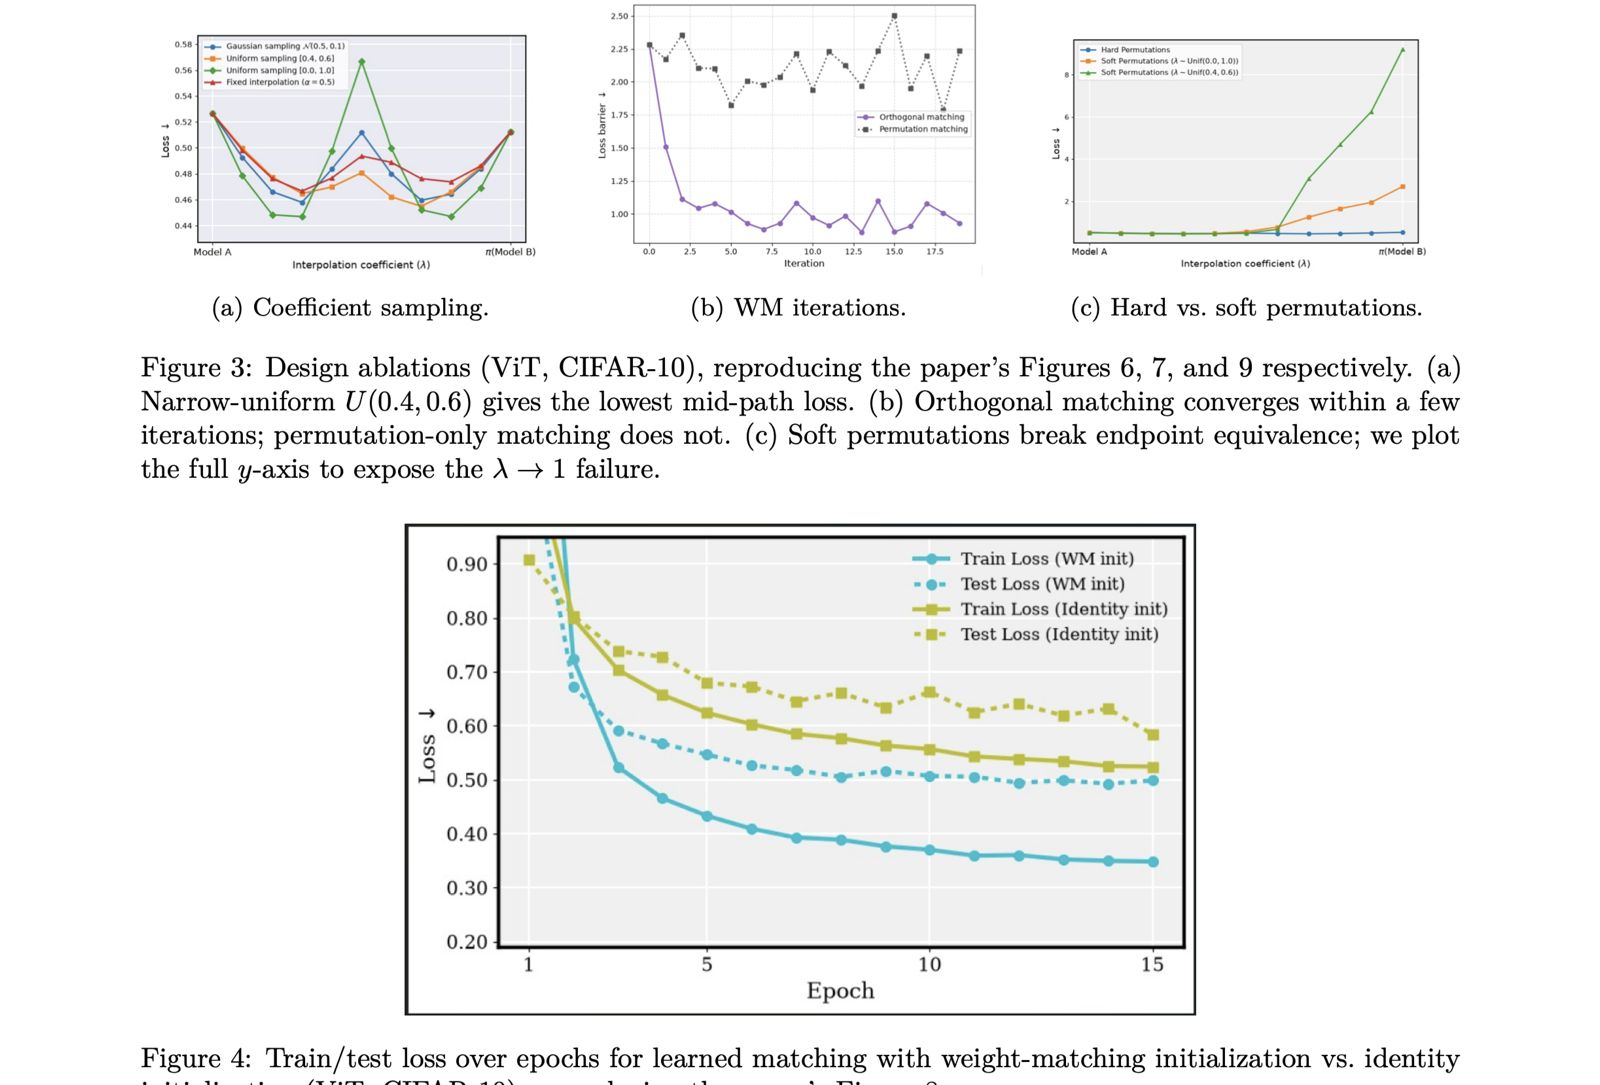
How Far Does Generalized Symmetry Alignment Reach? Reproducing and Extending Linear Mode Connectivity for Transformers

How Far Does Generalized Symmetry Alignment Reach? Reproducing and Extending Linear Mode Connectivity for Transformers

OpenReview · Tasmayu Swain, Krish Malik, Krishna Mudgal, Yajat Makhija

A reproducibility and extension study on Generalized Linear Mode Connectivity for Vision Transformers and GPT-2. Evaluated the limits of parameter symmetry alignment across out-of-domain code distributions, varying model depths, regularized weight matching, and adversarial endpoints.

mode connectivitytransformersreproducibility
// blogs

◆ published

DeepSeek-V3 Architecture From Scratch

MoE · MLA · Aux-Loss-Free Routing · MTP · PyTorch

A walkthrough reconstructing the core pillars of the DeepSeek-V3 architecture in PyTorch — from Multi-Head Latent Attention and auxiliary-loss-free expert routing to Multi-Token Prediction, grounded in the original papers.

deepseek-v3MoEMLAMTPpytorchread →
⧗ upcoming

On-Policy Distillation (OPD) for Post-Training Language Models

RL · Post-Training · Distillation · LLMs

An upcoming deep-dive into On-Policy Distillation — how OPD frames post-training of language models, where it differs from off-policy methods, and why the on-policy teacher signal matters for alignment and capability transfer.

OPDdistillationpost-trainingRL

// research projects

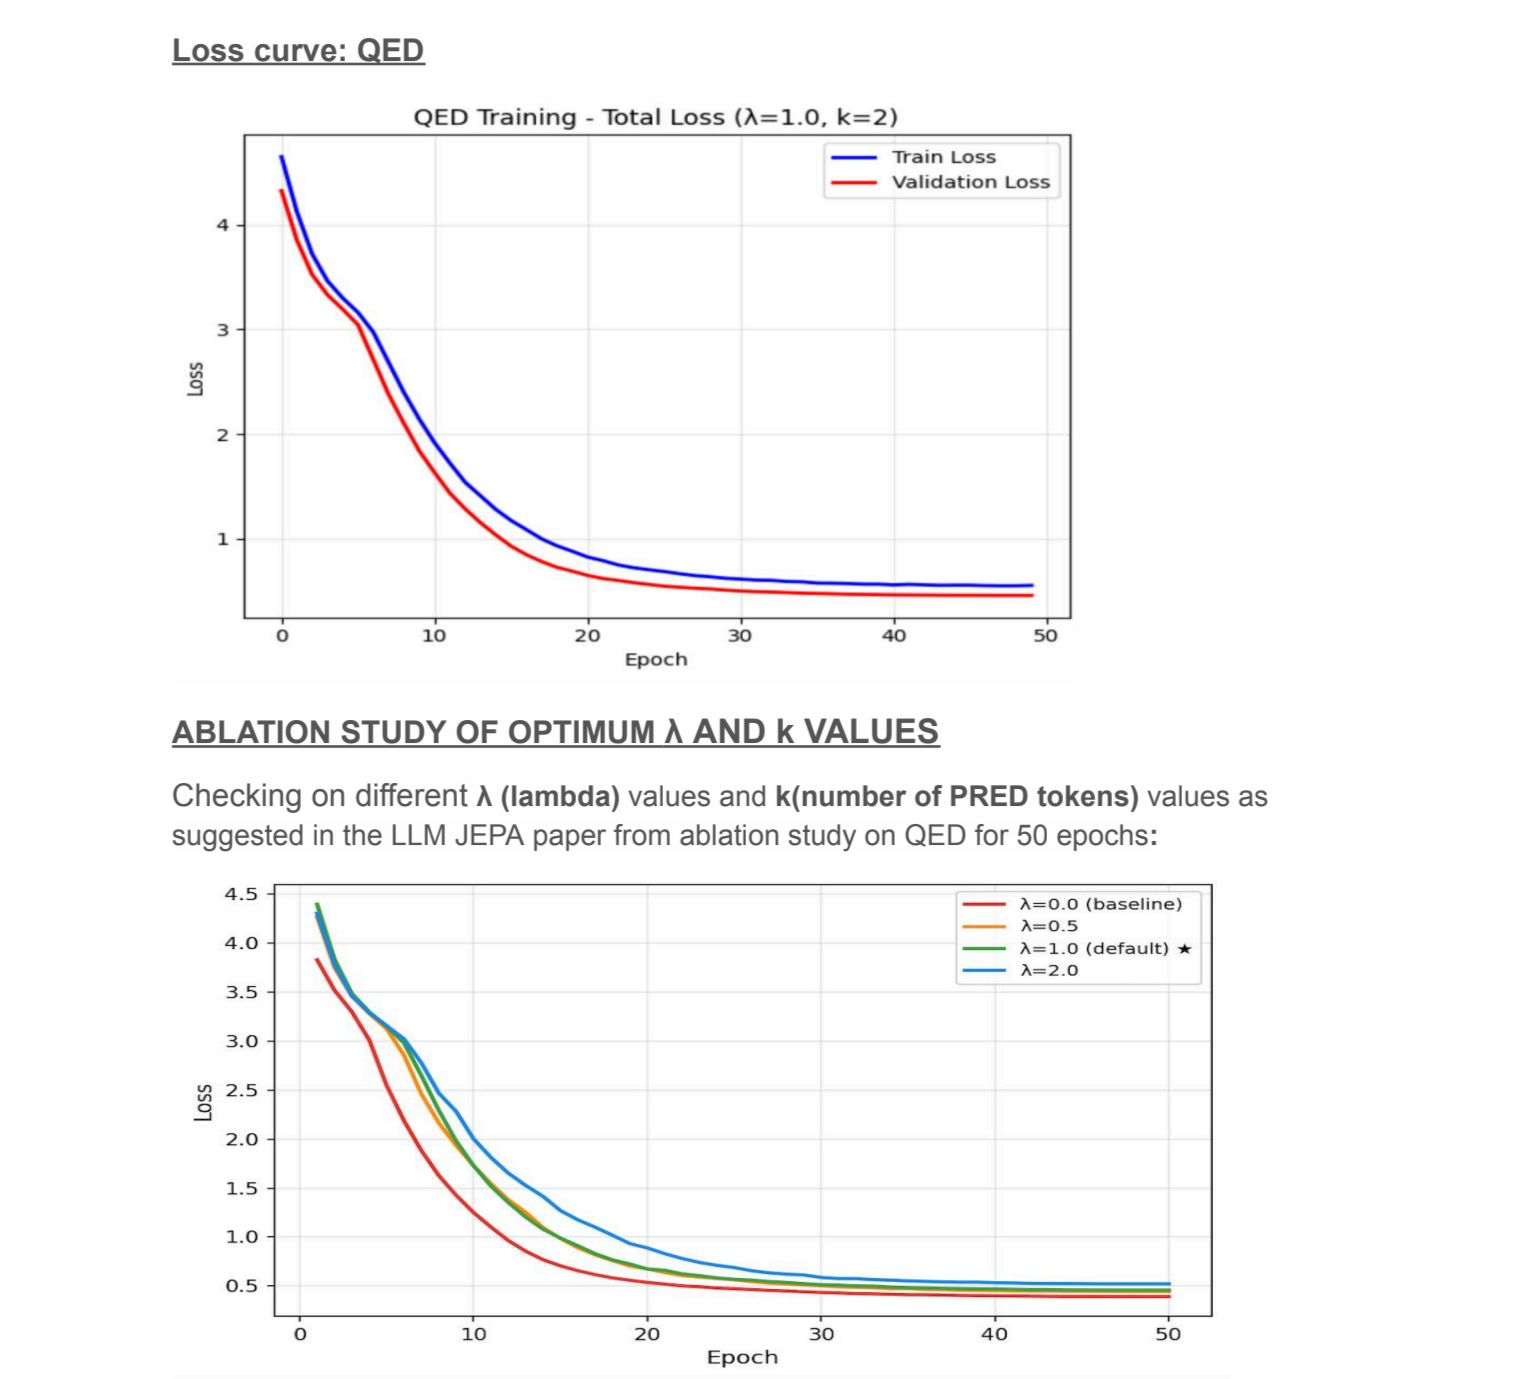
LM-JEPA for Squared Amplitude Calculation architecture diagram

LM-JEPA for Squared Amplitude Calculation

Joint Embedding Predictive Architecture · Scientific ML · Particle Physics

Built an LM-JEPA based framework to model squared amplitudes for particle interaction processes in high energy physics.

JEPAscientific mlphysicsopen →
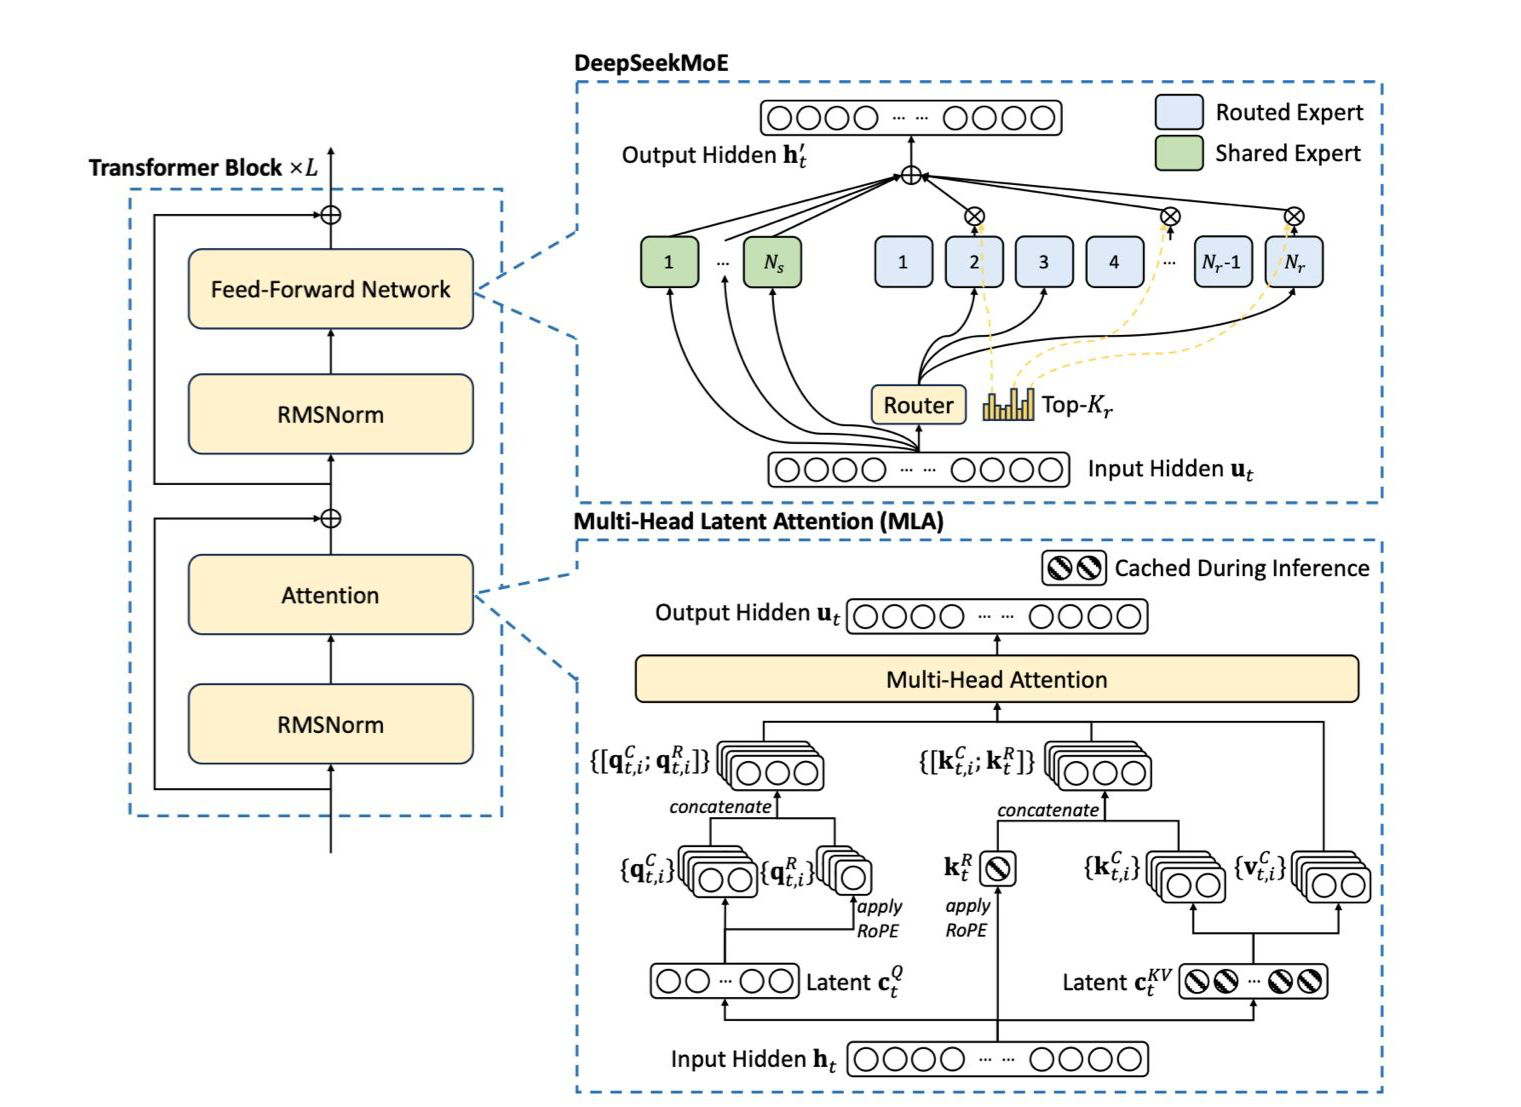
DeepSeek-V3 From Scratch architecture diagram

DeepSeek-V3 From Scratch

MoE · Multi-Head Latent Attention · PyTorch

Reimplemented the core DeepSeek-V3 architecture including optimized transformer blocks, then explored fine-grained expert routing, load balancing and Multi-Token Prediction (MTP).

MoEMLApytorchopen →

Nano Diffusion Language Model

Diffusion Models · ModernBERT · Generative Modeling

A compact diffusion-based language model inspired by the LLaDA paper: ModernBERT as mask predictor with random masking t ~ U[0,1] and 1/t loss weighting.

diffusionLLaDAgenerativeopen →
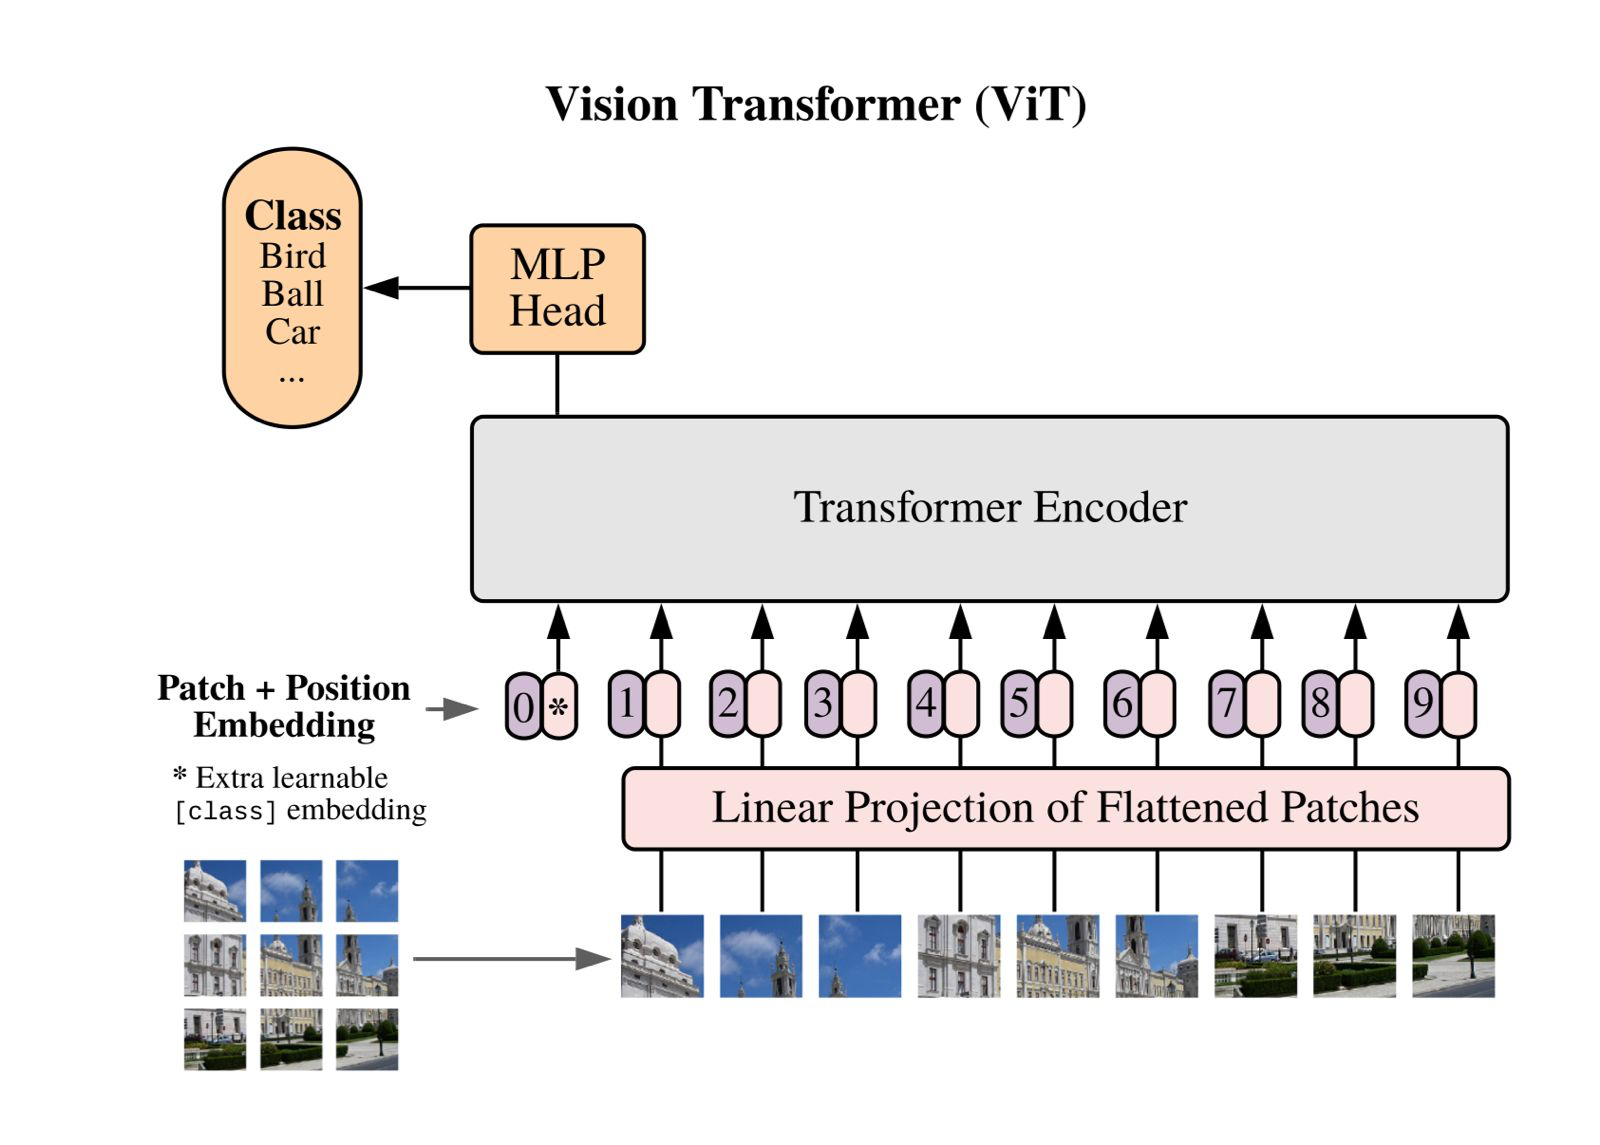
Vision Transformer From Scratch architecture diagram

Vision Transformer From Scratch

Computer Vision · Patch Embeddings · CLS Token

Full ViT pipeline built from first principles — patch projection, positional encoding, attention stack and classification head.

ViTvisionpytorchopen →

Physics-Informed Neural Networks

Scientific ML · Differential Equations · Neural ODE

Modeled projectile motion by integrating the governing physics equations directly into the network's loss function.

PINNneural ODEscientific ml

// hackathons

IIT Delhi AMD RL Hackathon
★ top 15 teams

IIT Delhi AMD RL Hackathon

Trained competing Question and Answer agents with SFT + GRPO from teacher-model data. Fine-tuned Qwen-2.5-7B on an AMD MI300X GPU.

GRPOSFTqwen-2.5-7B
HACKLLM · IIIT Delhi
★ top 50 / 110

HACKLLM · IIIT Delhi

Detecting LLM hallucination: a retrieval-augmented verification pipeline using Mistral-7B with DeBERTa-based evaluation.

RAGhallucinationmistral-7B

ISRO Bharatiya Antariksh Hackathon 2025

Built a PM2.5 estimation heatmap from ISRO MOSDAC and NASA environmental data sources.

geospatialremote sensing